
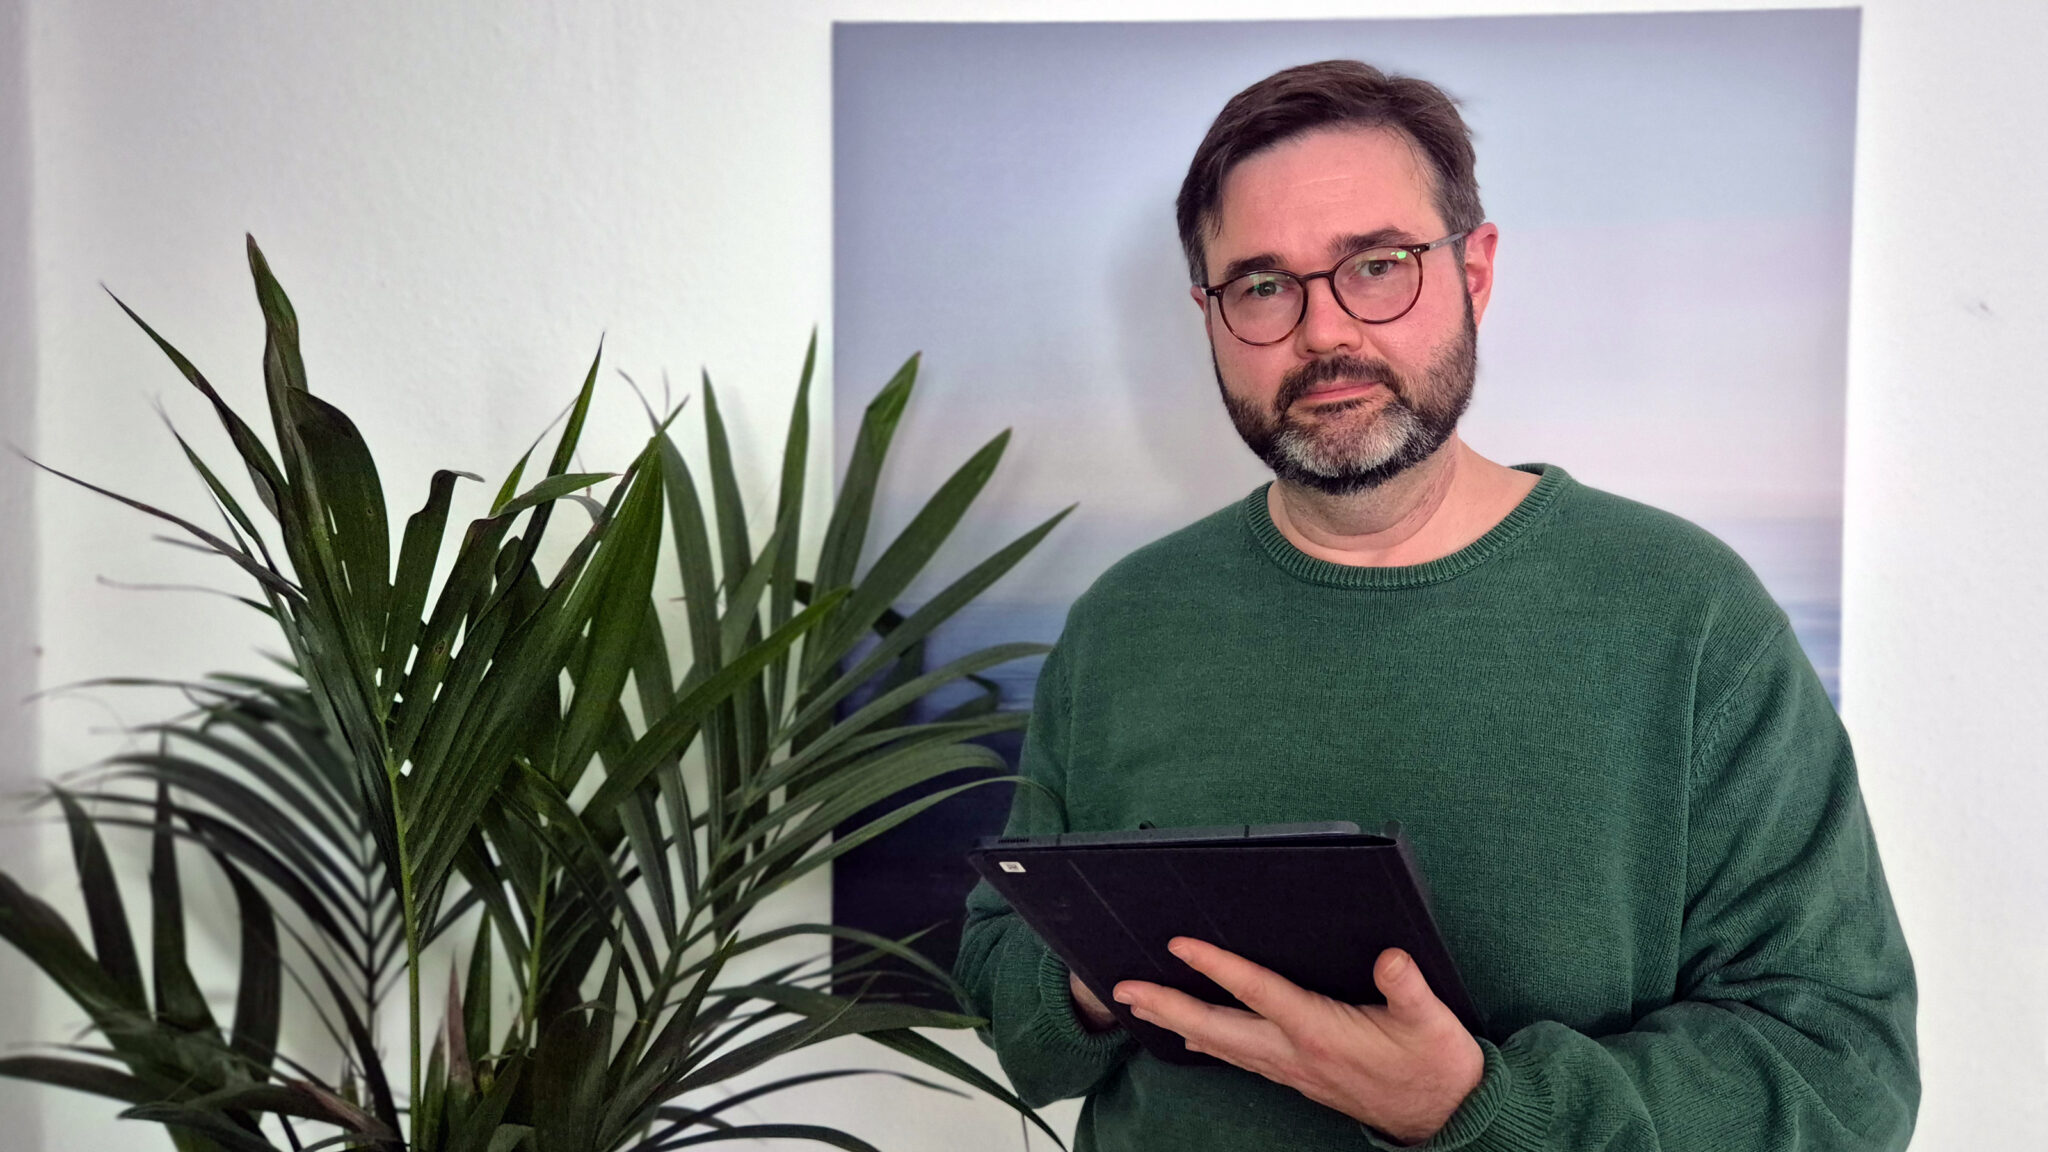
This interview is with Felix Römer, Founder, SmartKeys.
As a founder working at the intersection of content, ecommerce, and AI-enabled operations, what problems do you spend most of your time solving today, and what has given you the most useful perspective on smart work?
Most of my week goes to one problem wearing two costumes: work that exists only because other work exists.
In my day job, I lead e-commerce and IT at Simon Profi-Technik, a German online retailer for garden and forestry equipment. The visible work is the shop. The invisible work is everything around it: support tickets asking where an order is, price data that has to be checked before it goes live, reports someone assembles every Monday. None of it is hard. All of it is the ceiling on what the team can do.
At SmartKeys.org, the costume changes, but the problem does not. I run an online magazine about AI tools, SaaS, and how work is changing, and I run it alone. Every review requires weeks of testing, and every published article decays: prices change, features move, a statistic goes stale. Keeping a few hundred articles honest is exactly the same kind of scaffolding problem as the support queue, just with worse pay.
The most useful perspective came from doing both at once. The retailer keeps me honest about what a tool has to survive: seasonal peaks, an ERP that predates the tool, and colleagues who did not ask for it. The magazine gives me permission to break things before anyone depends on them. When I write a SaaS review, I know what the marketing page is hiding because I have signed a contract like that at work. When I automate something at work, I have usually already watched it fail on my own site first.
Smart work, in my experience, is not a productivity system. It is knowing which of your tasks are scaffolding and refusing to be proud of how well you do them.
What path led you to become a founder who tests new technology inside real workflows rather than treating it as a purely theoretical trend?
Mostly by being wrong about a trend once, expensively, and from the inside.
I trained as an application developer, freelanced in web development and SEO for six years, then ran my own e-commerce company selling licensed merchandise, mainly to the US. After that I spent four years as CIO of an energy startup building a blockchain-based trading platform. Smart people, real engineering, and a technology that was, at the time, mostly a slide. I learned what a trend looks like when you are standing inside it: the demos are always better than the operations, and nobody measures the second thing.
Then I went to Simon Profi-Technik in 2019, where the opposite is true. Nothing gets adopted because it is interesting. It gets adopted because spring arrives and the support queue triples. That environment ruined me for theoretical evaluation. If a tool cannot survive a season, its roadmap does not matter.
SmartKeys started in 2024 as a place to write that down. I had read too many “top ten tools” articles by people who had clearly never opened the products, and I wanted the version I would have wanted to read: what the second-cheapest plan really includes, where it breaks, who should skip it. That only works if you use the tool for real work first, so the site became a lab. Automations I later rolled out at the retailer I usually ran on my own site first, where the only person I could annoy was me.
The honest summary is that I did not choose to test inside real workflows. I just stopped trusting anything else.
When you assess a new AI or automation tool, how do you choose a real business task that is valuable enough to test but safe enough to learn from?
I run two tests, in this order: does it clear the hourly value bar, and can I undo it.
The first is the hourly value test. What does an hour of my time need to be worth for this task to belong in my hands? For most of what I do, the number is unforgiving. Updating a statistic across twelve old articles, converting a podcast transcript into show notes, first-line answers to “where is my order”: none of it clears the bar, so all of it is a candidate.
Valuable enough is easy. Safe enough is where most teams get it wrong, because they equate safe with unimportant and then test the tool on something nobody cares about. You learn nothing that way. My rule is that a good test task has to hurt a little, and it has to have three properties.
- Reversible: every change can be rolled back. On my site, the AI assistant logs every edit to a private post before it touches anything public.
- Observable: I can see the output before anyone else does. At the retailer, the support AI ran in note mode first, drafting replies only the team could see.
- Bounded: it touches one queue, one category, one week. Not the whole site, not the whole season.
If a task fails one of those three, I do not soften it; I pick a different task. If the tool fails halfway through the test, that failure is the result, not a reason to try harder. I cover the pattern in more detail in my piece on AI agent workflows, including the KPIs that told us a pilot was ready to leave the sandbox.
You have used AI to update content and support customers; what is the first process you would recommend a small team audit for automation, and what signals suggest it is a strong candidate?
Audit lookup work first. Any task where a person is not making decisions—just finding an answer that already exists in another system and typing it into a message.
At Simon Profi-Technik, that was first-line support: “Where is my order?”, “Can I have my invoice?”, “Which chain fits this saw?”. The answer to each lived in the ERP or the product database. A human was the bridge. This year we replaced the bridge with an AI workflow inside Zendesk using n8n, the current Gemini model, a direct ERP connection, and a knowledge base for the brands we carry. It now handles roughly two to three times the volume of one agent, around the clock, and humans now handle complaints and technical advice instead.
Four signals told me it was the right first candidate, and they apply to almost any team.
- The answer exists somewhere already. If the task needs judgment, it is not first.
- Volume spikes. Our tickets triple in spring. Automation earns its keep fastest where hiring cannot follow demand.
- The failure mode is cheap. A wrong tracking link gets corrected in one reply. A wrong refund does not.
- Someone is quietly annoyed by it. Ask the team which task they would delete if they could. That answer is usually more reliable than a process map.
One part people skip is what happens around the tool. The pilot was run by our most skeptical support colleague, with the right to stop it; he did not. Rollout without that step fails on people, not technology, which is most of what my guide to change management is about. The technical pattern, from pilot to production, is in my AI agent workflows playbook.
What practical safeguards have helped you keep AI-assisted work accurate and accountable, especially when the output affects customers or published content?
There are four, and the useful thing about them is that none require trusting the model.
- Make the AI visible. Customers of the retailer can see when a reply was written with AI assistance. That felt risky at first. It turned out to lower complaints, because people forgive a labeled assistant faster than a human who sounds like one.
- Score confidence, then route on it. Every support answer carries a confidence value. Below the threshold, or the moment a customer replies with something the system cannot place, the ticket goes to a person. Automation that cannot say “I am not sure” is not automation; it is a liability with good grammar.
- Log every change, and read the log, not the work. On SmartKeys.org, an assistant connected to WordPress updates stale numbers and fixes links. Each edit is written to a private changelog before it goes live. I review the log in ten minutes, which is the difference between saving time and moving it.
- Separate draft from publishable. My prompt library tags every prompt with what its output is allowed to be: “draft only” or “publishable after fact check.” Opinions, opening paragraphs, and any sentence with a number in it are always mine. If those are wrong, the reader was right to blame me, not a tool.
One more that is now law rather than preference: since August 2026, generated images in the EU need labeling. On my site that was easy, because anything showing a product, a person, or a real interface was already a screenshot. Where generated visuals make sense and where they do not is something I worked through in AI in creative work.
The pattern underneath all four is the same. Automate the preparation, keep the accountable decision with a person, and make sure you can see what happened.
As search and discovery increasingly involve AI summaries, what change can a business make to its existing content this week to become more useful, trustworthy, and easier to surface?
Rewrite the first sentence under every heading so it answers the heading. That is the whole week if you have a large site, and it is the change that moved the needle most for me.
Most business content warms up: two sentences of context, then the answer. AI summaries do not wait. They pull the passage that answers the question in one clean block, and if your block starts with “there are many factors to consider”, you are not in it. On SmartKeys.org I went through the articles that mattered and made every section lead with the direct answer, with reasoning after. It felt blunt. Nobody complained, and citations in Google’s AI Overviews went up.
Three smaller moves fit in the same week:
- Attach a source and a date to every number. “Studies show” becomes “Ahrefs, 300,000 keywords, April 2025.” I had to delete about a fifth of my statistics because I could not trace them. That deletion did more for trust than anything I added.
- Delete hedging where you actually know the answer. “Pricing varies” cannot be quoted. “Starter costs 29 dollars per user, checked August 2026” can.
- Add a short FAQ in plain language, five to ten questions people really ask. Google says you do not need special markup to appear in AI features, and my Search Console data agrees. The FAQ works because it forces you to write self-contained passages, not because of the schema.
What I would skip: llms.txt files, special AI markup, vendor visibility scores. I chased those first and they did nothing measurable.
The longer version, including how AI Overviews and assistants choose sources and how to measure it with the tools you already have, is in my guide to generative engine optimization.
What have failed AI or automation experiments taught you about recognizing when a promising tool is not actually the right fit for a business?
A tool being promising and a tool being right for you are two different questions, and the second is usually answered by a limit, not a feature.
My most instructive failures were small. I spent weeks on llms.txt files and AI-specific markup because the whole industry was talking about it. Nothing moved. The lesson was not “markup is useless”; it was that I had been optimizing for a mechanism I could not measure, on the word of vendors who could not either.
At the retailer the pattern was different. A tool would demo beautifully on a clean data set, then meet our ERP, which predates most of the internet, and stall on the first import. Roughly a third of what I test for SmartKeys.org never becomes an article for the same reason. It worked. It just did not survive contact with real data, real seasonality, or the second-cheapest pricing tier.
Three signals now tell me early that a fit is wrong.
- The tool needs the process to change to suit it, rather than the other way round. Sometimes that is correct. Usually it means the tool was built for a different business.
- I cannot see what it did. No log, no diff, no confidence score. If I cannot audit it, I cannot delegate to it.
- The limit lives in the documentation, not the pricing page. Send caps, API ceilings, export limits. I read those before the feature list now.
The hardest part is stopping. I have kept tools running past their usefulness because I had already invested the setup time. That is textbook sunk cost thinking, and I wrote the piece partly to talk myself out of it. The setup time is gone, whatever I decide. Only the next month counts.
Looking ahead, which smart-work trend do you believe founders and knowledge workers are underestimating, and what can they do now to prepare for it?
The customer is increasingly not going to read your website. An assistant will read it for them and then decide.
This is already true for information. Ask ChatGPT or Perplexity which tool to buy, and you get a named recommendation in eight seconds, drawn from whichever sources it trusts. It is about to become true for the purchase itself. Agentic commerce, where an AI assistant compares options, checks stock, and completes the order on the shopper’s behalf, has working payment rails as of this year. The first wave stalled on trust and on retailers’ data being unreadable to machines. The second wave will not.
Founders underestimate this because the numbers are still small. Knowledge workers underestimate it because it looks like a marketing problem. It is neither; it is a question of whether your business exists in a form a machine can act on.
What to do now, in order.
- Make your facts extractable. Prices, availability, specifications, and return terms should be stated once, dated, and published as text an assistant can quote. If your best information is in a PDF or behind a “contact us” form, you are invisible to the buyer’s agent.
- Become a source before you need to be. Being cited by assistants compounds slowly; the sites that will be cited in 2027 are restructuring their content this year.
- Decide what you will still do by hand. For retailers, product advice on complex machinery stays with people. That is not resistance; it is positioning. The assistant will route the hard questions to whoever answers them well.
I track this and related shifts in business trends on SmartKeys.org, and what strikes me every month is how much of the advantage goes to businesses that simply wrote things down clearly, early.
For a founder with limited time who wants to adopt ahead-of-the-curve techniques without chasing every trend, what simple operating rule has been most effective for you?
One tool, two weeks, one real task. Then a decision.
That’s the whole rule. I pick one tool, plug it into something I already have to do, use it for two weeks, and at the end I either keep it, drop it, or write about it. No sandbox, no demo account, no trying three tools in parallel. Parallel testing feels efficient but teaches me nothing, because I never get past the onboarding for any of them.
Two conditions make it work. The task has to hurt a little—if I could do it faster by hand, the test is meaningless. And the tool has to earn the second week. If it fails halfway through the first week, that failure is the review, and I stop.
The rule protects me from the two ways founders lose time to trends. The first is chasing every launch. With one slot open at a time, most launches simply wait, and by the time the slot is free, half of them have proven themselves irrelevant without my help. The second is the quiet accumulation of tools that nobody canceled. A decision at the end of every test keeps the stack small.
The other half is protecting the time to run the test at all. I use a daily highlight: one task that goes on the calendar and gets defended against everything else. The two-week test usually lives there for a few of those days. Without a protected slot, testing is the first thing that gets cut when the season starts, and then you are evaluating tools from the demo video again.
More of what has survived that filter is in productivity tips on the site. Most of it is boring, which I have come to think is a good sign.
Thanks for sharing your knowledge and expertise. Is there anything else you’d like to add?
One thing I would say to anyone in a similar position: running a small publication alongside an operating role is not a distraction from the job. It is the cheapest R&D department you will ever have.
Everything I roll out at Simon Profi-Technik has typically been broken on SmartKeys.org first, where the only casualty was my weekend. Everything I write there is more useful because I have to live with the consequences of the same decisions on Monday. If you can find a version of that loop — a newsletter, a side project, or a public log of what you tried — it will make you better at your actual work faster than any course.
If you want to see what that looks like in practice, the site covers four things:
- Independent SaaS reviews that lead with who should skip the tool.
- Business trends that I try to write without the hype.
- Future of work, which right now means the four-day week, return-to-office data, and what AI is doing to entry-level jobs.
- Productivity, mostly the boring habits that survived my own testing.
Every article carries the date it was last checked, and I replace any statistic I cannot verify rather than keep it. There is a newsletter and a podcast for anyone who prefers those formats.
Thanks for the questions. A few of them made me write down rules I had only been following by instinct, which is usually how I find out whether they are actually rules.